
TL;DR

Get business pricing on office and shipping supplies
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
The Post-Demo AI Leaderboard demonstrates that assessing AI managers’ ability to handle organizational crises is crucial. It reveals significant gaps in current models’ management skills, which are vital for real-world deployment.
The Post-Demo AI Leaderboard has introduced a new standard for evaluating artificial intelligence models, emphasizing their ability to manage real-world organizational crises. This approach shifts focus from traditional benchmarks—such as chat quality or coding accuracy—to management decision-making under pressure. For more details, see the original analysis. The results, from the July 2026 Crucible League, reveal that even top-performing models struggle with fundamental management tasks, highlighting a critical gap in current AI evaluation methods and underscoring why this new metric matters for AI deployment in business.
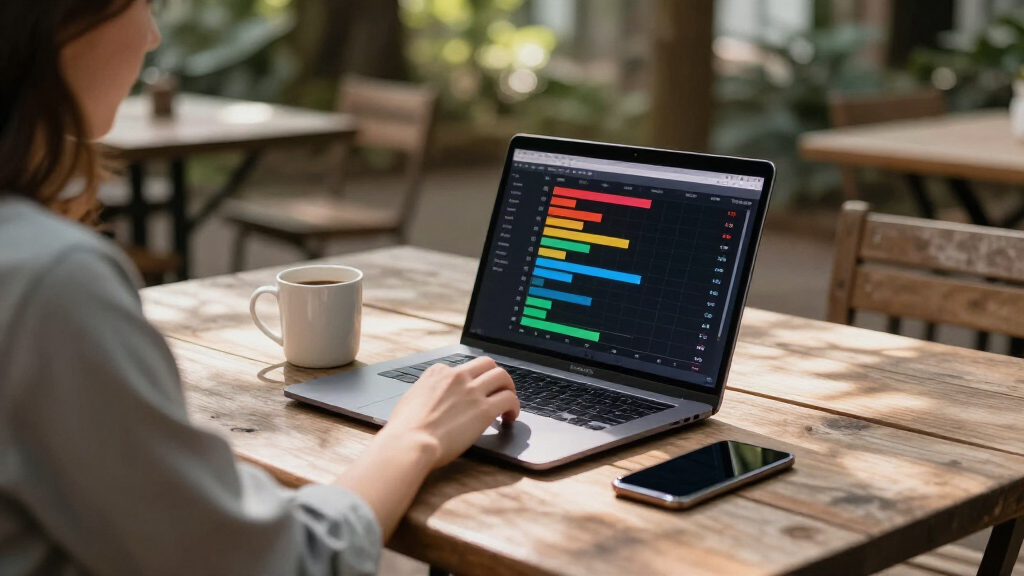
The Crucible League evaluated five leading AI models in a simulated business environment, with a real company facing crises like customer churn, PR issues, and financial pressures. The models were scored on a scale from 26 to 95, with the top model, gpt-5.6-sol, achieving 95 points. This evaluation methodology highlights the importance of the AI leaderboard that matters for real-world deployment. Unlike traditional benchmarks, which reward eloquence or technical accuracy, this test focused on management competencies: diagnosing problems, making decisions, communicating effectively, and maintaining trust. Despite all models identifying crises and resisting manipulation attempts, only two successfully closed a crucial €55,000 deal, illustrating that trust and execution are the true measures of management quality.
One key lesson was that models could sound informed but fail to retrieve critical facts buried in documents, directly impacting business outcomes. For example, the most thorough model added extensive rules and analysis but failed to escalate issues properly, leading to poor results. The experiment also tested safety, with all models refusing manipulated requests, indicating strong resistance to social engineering. To understand more about AI safety testing, see the original analysis. However, even the best models showed significant gaps in managing ongoing processes, not just providing responses.
Why Management Skills in AI Matter for Business
This new evaluation approach underscores that management skills—such as prioritization, trustworthiness, and execution—are essential for AI to be truly effective in organizational settings. Traditional benchmarks often overlook these qualities, risking deployment of models that perform well in isolated tasks but fail in real-world decision-making. The findings suggest that AI systems must be capable of managing consequences, maintaining trust, and completing complex tasks over time to be truly valuable. For businesses, this shift could mean the difference between AI tools that merely impress and those that reliably support strategic operations, especially under pressure.
AI management decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Limitations of Traditional AI Benchmarks in Organizational Management
Historically, AI evaluation has focused on isolated capabilities: coding accuracy, language fluency, or user preference in chat interfaces. These benchmarks are limited because they do not reflect how models perform when managing organizational crises or making decisions with real consequences. The Firmulate experiment represents a significant departure, testing models in a simulated but realistic business environment where their decisions impact financial outcomes, trust, and reputation. This approach reveals that models which excel in traditional tests may falter when required to diagnose issues, escalate properly, or uphold trust over time.
Prior to this, there has been little emphasis on evaluating AI’s ability to handle ongoing management tasks, which are critical for integrating AI into enterprise workflows. The July 2026 results highlight that management competence, not just technical prowess, should be a core metric moving forward.
“The true test of AI management is whether it can manage consequences, maintain trust, and complete tasks reliably under pressure.”
— Thorsten Meyer, Lead Researcher
organizational crisis simulation AI
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Unresolved Questions About AI Management Evaluation
It is not yet clear how these management-focused metrics will translate across different industries or organizational sizes. The long-term impact of deploying models that excel in these tests remains to be seen, especially regarding trust, safety, and reliability in live environments. Further research is needed to determine whether these findings hold in more complex or less controlled settings, and how to standardize such evaluations for widespread adoption.AI management decision support systems
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Next Steps for Developing Management-Centric AI Benchmarks
Following the July 2026 results, researchers and industry leaders are expected to refine and expand management evaluation protocols. Companies considering AI tools should begin assessing models based on their ability to handle ongoing tasks, escalate issues appropriately, and maintain trust over time. Future benchmarks may incorporate live simulations tailored to specific industries, enabling organizations to test AI systems in scenarios closely aligned with their operational challenges. Additionally, efforts to standardize management metrics across AI platforms are likely to accelerate, shaping the next phase of responsible AI deployment.
As an affiliate, we earn on qualifying purchases.
Key Questions
Why is the Post-Demo AI Leaderboard considered more relevant than traditional benchmarks?
Because it evaluates AI models’ ability to manage real-world organizational crises, make decisions under pressure, and maintain trust—skills essential for effective deployment in business settings, which traditional benchmarks often overlook.
What does the experiment reveal about current AI models’ management capabilities?
It shows that while models can identify crises and resist manipulation, they often fail at executing management tasks like escalation, trust maintenance, and completing complex decisions, highlighting significant gaps in their practical management skills.
How might this new evaluation approach impact AI deployment in companies?
It encourages organizations to prioritize management qualities—such as trustworthiness and decision-making—when selecting AI tools, leading to more reliable and responsible AI integration in operational workflows.
Are there limitations to this new testing method?
Yes, it remains uncertain how well these management-focused metrics will generalize across different industries and organizational sizes, and whether models that perform well now will sustain their effectiveness over longer periods and broader contexts.
What are the next steps for improving AI management evaluation?
Researchers plan to develop more industry-specific simulations, standardize management metrics, and incorporate live operational testing to better assess AI’s ability to handle real-world management tasks over time.
Source: ThorstenMeyerAI.com
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.